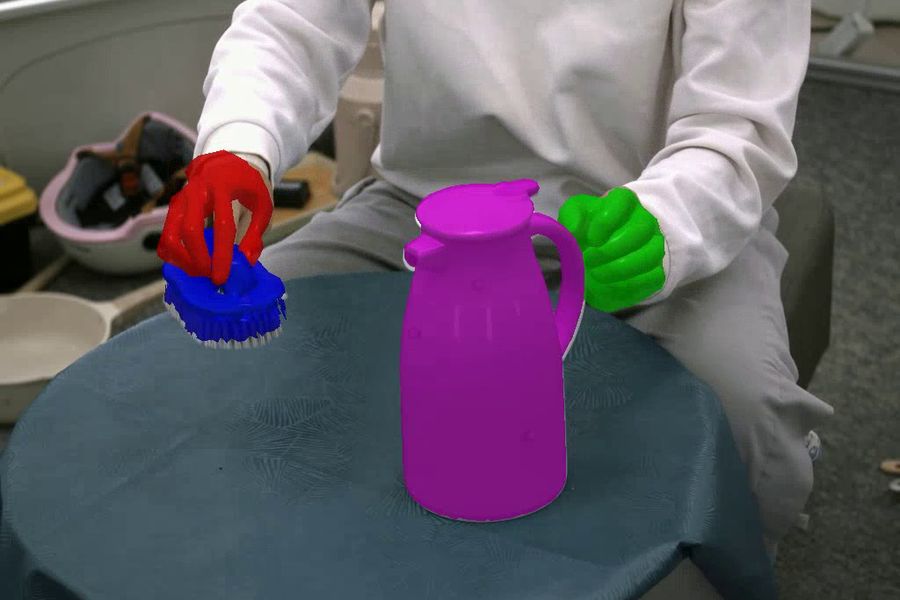
Frame from the TACO dataset, Tsinghua University, CC BY 4.0.
CC BY 4.0
The publisher's licence permits commercial use and redistribution, with attribution.
Version 1 is on a Dropbox shared folder; the smaller pre-release (244 sequences, 8 views) is on OneDrive; BaiduNetDisk backup needs code kg7j. Folder-level browsing only, no stable per-file URLs; total size not published. Camera count is 1 egocentric plus 12 allocentric in V1 (8 in pre-release).
Specification, as published
- Hours (derived)
- 48 h
- Episodes (stated)
- 2,317 episodes
- Scale
- 2.5K motion sequences
- Task
- Cleaning, Cooking & food prep, Other
- Environment
- Indoor – home, Indoor – studio
- Modality
- RGB, Depth, Hand pose, Object pose
- Capture
- Egocentric
- In frame
- Person hands
- Captured in
- Asia
- Embodiment
- human
- Resolution
- 1920x1080 (egocentric depth stream)
- Formats
- MP4, Pickle, NPZ/NumPy, Other
- Hosted on
- Dropbox
Figures are the publisher's own. Kinetic Blocks has not measured this dataset. Derived from the paper: 5.2M frames at 30 Hz, summed across the twelve third-person cameras and the egocentric camera.
About this dataset
TACO records two-handed human interactions where a tool acts on a target object, captured in real daily-life settings by an egocentric RGB-D camera and a ring of 8 to 12 fixed RGB cameras synchronised with optical motion capture. Every sequence carries 3D hand and object meshes, poses, 2D masks and a tool-action-object label. The full release holds 2,317 sequences over 151 triplets and 206 high-resolution object models. No robot appears; the data targets action recognition, motion forecasting and grasp synthesis.
Publisher's own task names: compositional action recognition, hand-object motion forecasting, cooperative grasp synthesis, dust, stir, brush.
What Kinetic Blocks did, and did not do
Indexed and linked from the publisher. Not hosted, verified or graded by Kinetic Blocks. The publisher's terms govern. The licence shown is the one stated on the publisher's page, linked above. Nothing on this page is a claim by Kinetic Blocks.
Want the verified ones too?
Request access to the marketplace, where every paid listing is verified against its files and graded before it goes on sale.